Your robots.txt Is Probably Blocking the Wrong AI Bots. GPTBot Is Not OAI-SearchBot.
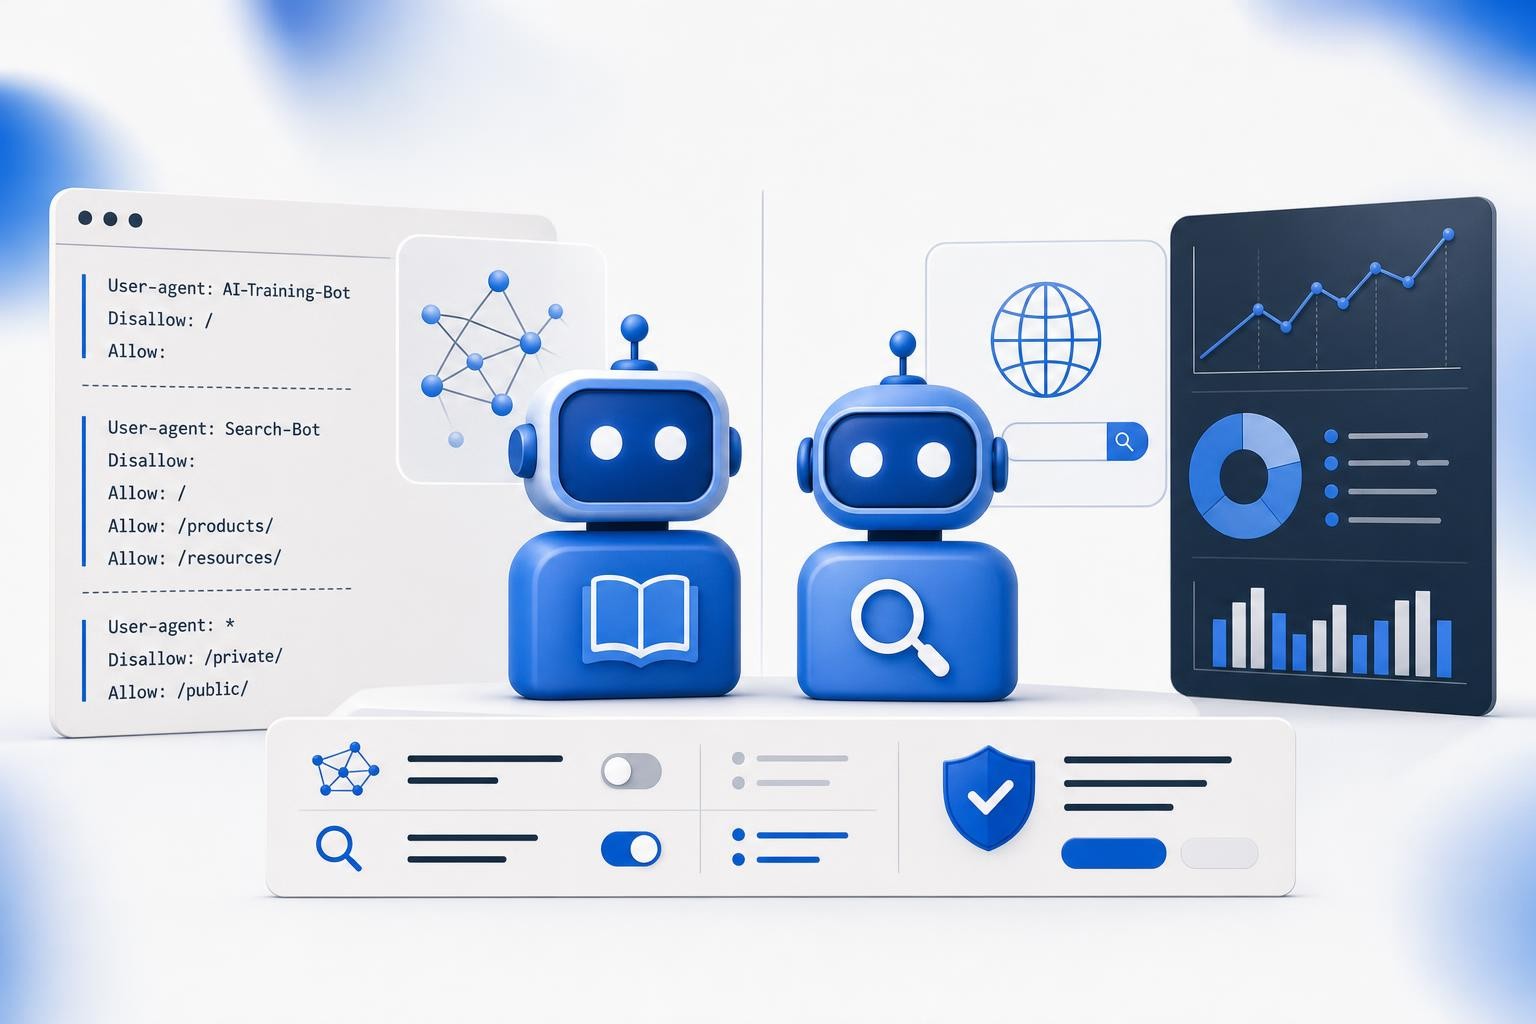
Most robots.txt advice for AI bots treats them as one group: block them or allow them. The data says the web is already splitting them in two, and B2B teams that don't are making an expensive mistake in one direction or the other.
Training bots and search bots are different jobs
A September 28, 2026 snapshot of 4,242 robots.txt files from Cloudflare Radar, analyzed by TechnologyChecker, shows how sites actually treat them. GPTBot, a training crawler, was named under Disallow 520 times against 326 Allow, a 1.60 to 1 ratio. ClaudeBot was 1.58 to 1. OAI-SearchBot, a search crawler, was 0.91 to 1, meaning slightly more sites allow it than block it. (TechnologyChecker)
The trend is toward opening up, not locking down. GPTBot's explicit Allow share rose from 2.51% to 7.69% in twelve months, and its block-to-allow ratio fell from 2.24 to 1 to 1.60 to 1 between the Q2 and Q3 closes. (Note the source flags September figures as provisional.) (TechnologyChecker)
Search-type crawling is the growing share
Search and user-triggered requests rose from 6.51% of AI crawl activity in Q2 2026 to 11.92% in Q3, while training made up 47.62%. (TechnologyChecker) Separately, a Zen Media report citing Cloudflare Radar said sites on Cloudflare's network denied 13.47% of AI bot requests in Q3 2026, up from 5.98% in Q3 2025; that figure is preliminary. (Agile Brand Guide)
Why it matters: the bots that fetch pages to answer a live buyer question are the ones that put your content in front of a prospect. Blocking them to stop model training is a different decision, with different stakes.
A blanket 'Disallow' on AI user agents, or a CDN default that blocks them, can remove you from AI answers without any warning in your analytics.
The trade-off is real
The same dataset shows why teams block. Crawl-to-referral ratios in Q3 2026 were 988 pages crawled per referral for Anthropic, 309 for OpenAI, 1,083 for Perplexity and 4.9 for Google. (TechnologyChecker) AI crawlers take far more than they send back. That argues for a deliberate policy, not for blanket blocking of everything that might carry a buyer.
A policy a lean team can actually run
Read your current robots.txt and any CDN or WAF bot rules. Many sites are blocking bots they never meant to.
Choose whether you accept your content being used for training (GPTBot, ClaudeBot) independently of whether you want to appear in AI search answers (OAI-SearchBot and similar).
Pricing, comparison, product and docs pages are what buyers ask AI about. Gated content can't be cited.
Re-test with the bots' published user agents and check server logs for fetches after you edit robots.txt.
Vendors add and rename crawlers. Put the check on a calendar.
The point
You don't need a single rule for "AI bots." You need two: one for who may train on your content, and one for who may read it to answer a buyer. Get the second one wrong and you are invisible exactly where B2B research now starts.
Is GPTBot the same as OAI-SearchBot?
No. GPTBot is classified as a training crawler; OAI-SearchBot is a search crawler. Sites treat them differently, and you can too.
Will blocking GPTBot remove me from ChatGPT answers?
Training and search access are separate user agents, so blocking one does not automatically block the other. Verify against each vendor's current documentation.
How often should I review AI crawler rules?
At least quarterly, and whenever you change CDN or WAF settings, since defaults can block bots silently.
Related
Google's 13-Day Spam Update and New AI-Content Guidance: A Quality Gate for B2B Teams Publishing With AI
Google's September spam update ran 13 days and 16 hours, and its AI-content guidance was refreshed in early October. A pre-publish quality gate for B2B teams that write with AI.
51% of Marketing Teams Run AI Agents. Only 6.5% Benchmark Them Against a Metric.
51.1% of marketing organisations use AI agents, but only 6.5% benchmark AI investments against defined metrics. A lean-team scorecard for proving what agents actually do.
AI Overviews Now Appear on 83% of Branded Searches. Your Brand SERP Needs a Defense Plan.
Ahrefs found AI Overviews on 82.91% of US desktop branded searches, and Semrush puts commercial-keyword coverage at 88%. Here is how a lean B2B team should defend its brand results page.